The reported gain is about serving an agent workload
Cognition says an early test of NVIDIA Vera Rubin NVL72 on CoreWeave delivered up to 4.8 times the total token throughput of a GB200 NVL72 baseline for SWE-2 inference workloads. The test sampled software-engineering tasks from FrontierCode and used AI agents to solve them. Cognition runs training, reinforcement learning and production inference for its Devin software engineer on CoreWeave.
That number describes tokens served across the workload. It does not mean a Devin model completed coding tasks 4.8 times faster or became 4.8 times more capable. The companies present this as an early benchmark, so it should be read as a vendor-reported infrastructure result rather than a public independent evaluation. Source: https://blogs.nvidia.com/blog/coreweave-agentic-ai-vera-rubin/
Agents need isolated places to run tools
A coding agent does more than generate text. It starts processes, runs tests, edits files and may need to explore several possible fixes at once. Each run needs a controlled environment so one attempt cannot interfere with another. CoreWeave says a Vera CPU rack contains 128 CPUs and 11,264 cores, enough for more than 11,000 concurrent one-core environments.
In its tests, CoreWeave reports more than three times faster sandbox startup on Vera CPUs and a 1.7-times performance gain across passing Terminal-Bench tasks. Faster startup can matter when a system is launching thousands of isolated attempts, even when the model itself is unchanged. These figures also come from the companies’ own testing.
Why this launch is about the whole system
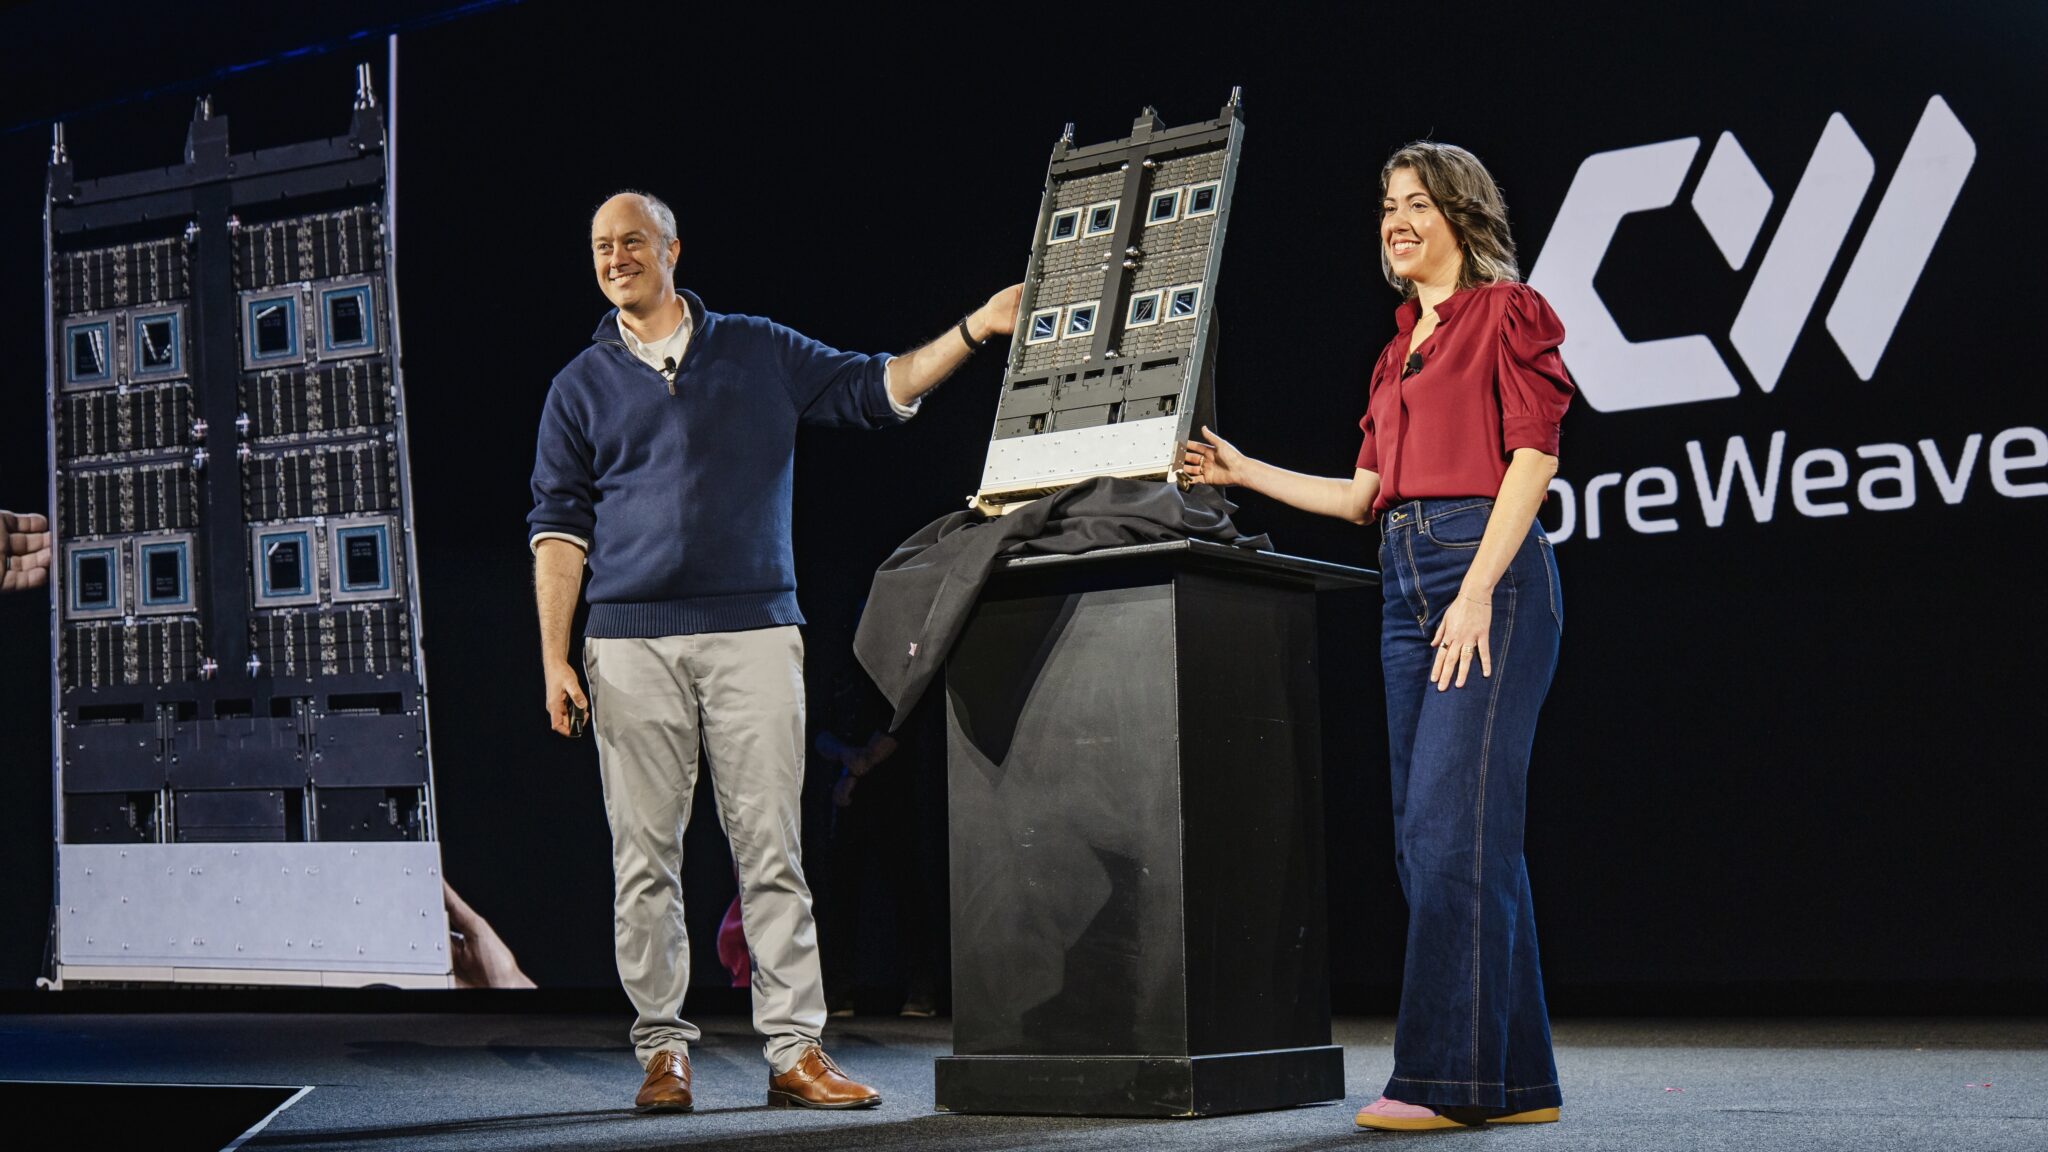
CoreWeave announced production availability of Vera Rubin NVL72 on its cloud and named Cognition as its first production customer. The announcement also introduces CoreWeave Forge, a connected environment for training, evaluating and improving models and agents. NVIDIA describes the rack, networking, CPU environments and inference tools as one system built around the long contexts and high concurrency of agent workflows.
For developers, the practical question is whether the extra throughput and faster sandbox launches lower the cost or waiting time of real tasks. The announcement provides early company benchmarks, but not enough independent data to settle that question. It does show why infrastructure can affect an agent product even when the model weights stay exactly the same.
Source published September 30, 2026. Coverage is based on the maker’s announcement and demonstration.